Why Flux 3 Matters for Real-World AI
In the last few years, the pace of progress in generative AI has been hard to keep up with. Every few months, a new model claims to be better, faster, or more capable than the last. But most of these models still operate in silos. You have one model for generating images, another for video, and yet another for audio. That fragmentation is a problem if you are trying to build systems that need to understand and generate across multiple modes of communication. This is where flux 3 enters the picture.
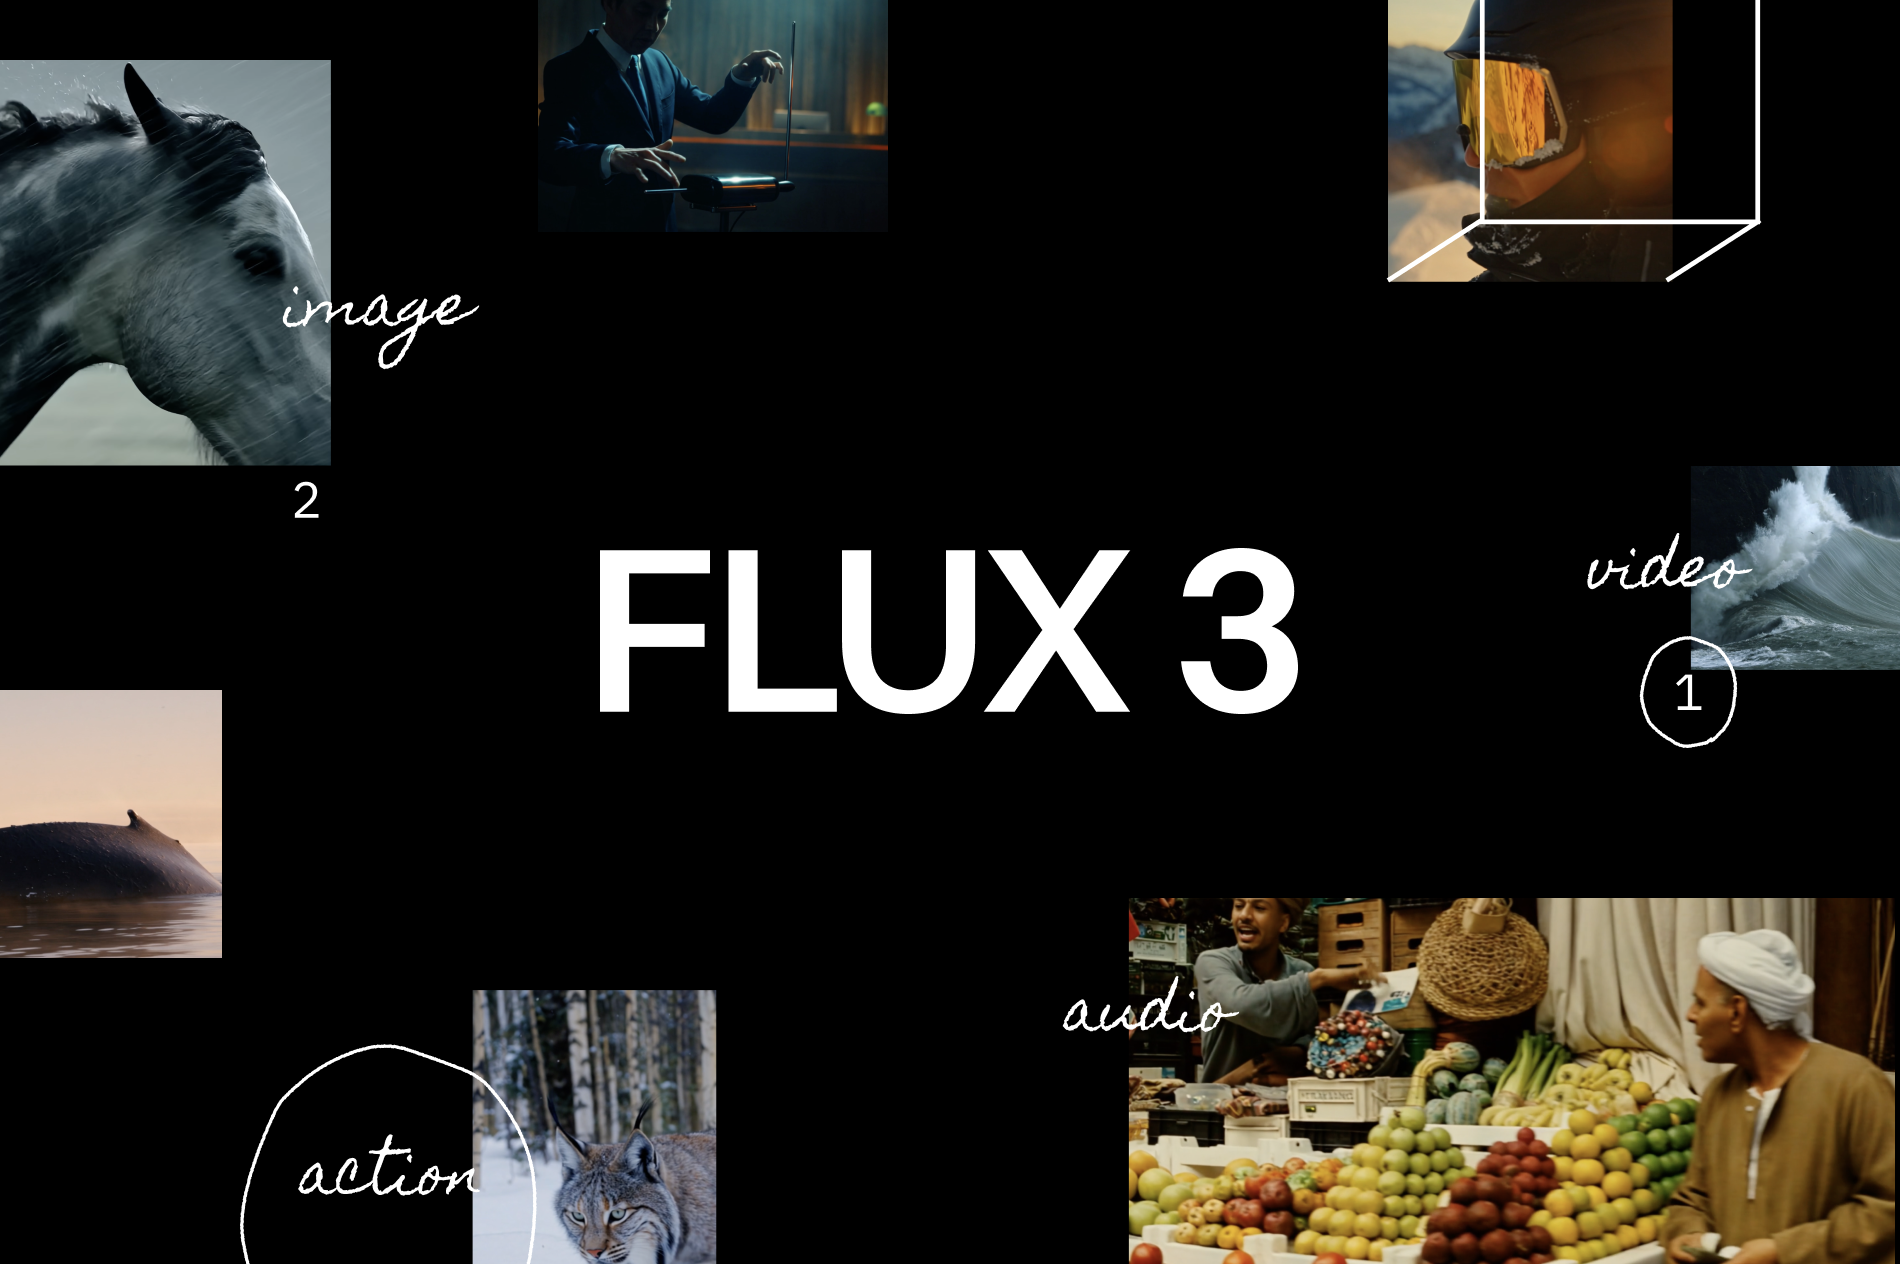
Flux 3 is a multimodal foundation model developed by Black Forest Labs. It is designed to handle image generation, video generation, and audio generation within a single unified architecture. That is a meaningful departure from the current norm, and it has implications for how we think about real-world AI. This article explores what that means in practice, what trade-offs are involved, and why the approach matters beyond the hype.
What Makes a Foundation Model Multimodal
A foundation model is a large-scale neural network trained on broad data that can be adapted to a wide range of downstream tasks. Most foundation models today are unimodal. They handle text, or they handle images, but not both in the same integrated system. Multimodal foundation models aim to bridge those gaps. They learn representations that span multiple modalities, so that knowledge from one domain can inform another.
Flux 3 is built on a combination of diffusion models and transformer architectures. Diffusion models have become the standard for high-quality image generation, while transformers excel at sequence modeling and natural language processing. By combining these in a unified architecture, Flux 3 can take a text prompt and produce not just a static image, but also a video clip or an audio track that matches the description. That cross-modal learning is not just a neat trick. It allows the model to understand concepts more deeply because it sees them expressed in multiple forms.
Why a Unified Architecture Matters
Most current workflows for generating media rely on a pipeline of specialized models. You might use one model to generate an image, then feed that image into another model to animate it, and then send the result to a third model for audio. Each step introduces latency and potential quality loss. More importantly, the models have no shared understanding of the content. The video model does not know what the image model intended, and the audio model has no context about the scene.
A unified architecture changes that. When a single model handles image, video, and audio generation, it can maintain consistency across modalities. The video knows where the objects are because it shares the same internal representation as the image generator. The audio can be aligned to the motion because the model understands the temporal structure of the video. This is where visual intelligence becomes practical. You are not stitching together outputs from different systems. You are working with one coherent model that generates a complete sensory experience.
Practical Applications and Real Trade-offs
So where does this matter in practice? Consider a few concrete scenarios:
- A game developer needs to generate assets for a virtual environment. Instead of using separate tools for textures, animations, and sound effects, they can prompt a single model to produce all three in a consistent style.
- A filmmaker wants to storyboard a scene with rough visuals and a scratch audio track. A multimodal model can generate the visuals and the audio together, keeping timing and mood aligned.
- A robotics team simulates interactions in a virtual world. The model generates visual scenes, audio cues, and motion trajectories that match the same physical rules.
These are not distant possibilities. They are the kind of tasks that real-world AI systems are already being built to handle. But there are trade-offs. A unified model is larger and more expensive to train and run than a set of smaller specialized models. Model scalability becomes a real constraint. The compute cost for training a single model that handles three modalities is higher than training three separate models, at least initially. The bet is that the benefits of cross-modal learning and consistency outweigh that cost in the long run.
There is also the question of evaluation. How do you measure whether a model that generates images, video, and audio is better than separate models? Standard benchmarks exist for each modality in isolation, but there is no widely accepted benchmark for combined multimodal quality. Teams working with flux 3 need to think carefully about their own evaluation criteria, and that is not a trivial task.
How Diffusion Models and Transformers Come Together
The technical architecture behind flux 3 is worth understanding at a high level. Diffusion models work by gradually adding noise to data and then learning to reverse that process. They have been extremely successful in image generation and are now being applied to video and audio. Transformers, on the other hand, process sequences of tokens and have become the backbone of natural language processing and computer vision architectures.
By combining these two approaches, flux 3 can handle both continuous data like images and audio, and discrete data like text tokens. The unified architecture uses a shared latent space where representations from different modalities can interact. That shared space is what enables cross-modal learning. When the model learns to generate an image from text, it also learns something about how that image relates to sound and motion. That knowledge transfers when it is asked to generate video or audio from the same text prompt.
This is not just about having one model that can do everything. It is about having a model where the learning in one modality improves the others. That is a fundamentally different approach from training separate models and trying to align their outputs post hoc.
Inference, Latency, and Deployment
AI inference for a model of this scale is not trivial. Running a multimodal model that can generate video in real time requires significant hardware. Black Forest Labs has focused on optimizing inference for practical deployment, but the reality is that not every team will have the infrastructure to run the largest version of the model locally. Cloud-based inference and API access will likely be the primary way most developers interact with the model.
That said, the model is designed to be scalable. Smaller variants can be deployed for tasks that do not require the full multimodal capability, and the model can be fine-tuned for specific domains. That flexibility makes it suitable for a wider range of applications, from research prototyping to production systems.
The Role of Data and Training
Training a multimodal foundation model requires vast amounts of paired data. You need text that describes images, videos that align with audio, and so on. Black Forest Labs has curated large datasets for this purpose, but the quality of the data is as important as the quantity. Noisy or misaligned data leads to a model that generates inconsistent outputs. This is a challenge that the entire field of generative AI is still grappling with.
One advantage of a unified architecture is that it can learn from data that is not perfectly aligned across modalities. If a model has a shared representation space, it can use weak supervision to infer relationships. For example, a video with ambient audio might not have explicit captions, but the model can still learn to associate the visual content with the sound. That ability to learn from less structured data is a significant practical advantage.
Looking Ahead
Flux 3 represents a step toward more integrated AI systems. The approach of combining diffusion models and transformers into a single multimodal foundation model is not the only path forward, but it is a well-motivated one. The real test will be in how well it performs on real-world tasks that require understanding and generating across modalities. Early results suggest that the consistency and coherence of outputs are noticeably better than what you get from stitching together separate models.
For developers and researchers working on computer vision, natural language processing, or any application that involves multiple types of media, flux 3 is worth evaluating. It is not a magic bullet. The model is large, the inference costs are real, and the evaluation standards are still being developed. But the direction is clear. The future of generative AI is multimodal, and unified architectures are the most promising way to get there.
